
Keywords versus conversational prompts
The way people search in ChatGPT depends a lot on how certain they already are about what they want. When the destination, product or answer is already clear, behaviour can look remarkably similar to traditional search: short, direct and often keyword-like. But when people are still researching, comparing options or trying to make a decision, something different happens. They add context, explain what matters to them and ask follow-up questions. Search starts to become a conversation.
What the evidence draws on
This article pulls together a few different sources to build the picture:
- Semrush clickstream data
- Research from OpenAI in partnership with Harvard, Duke and NBER
- Behavioural data from ShareChat and WildChat
It combines measured findings from these sources with an explicitly labelled illustrative model of how behaviour shifts depending on intent.
Search behaviour is changing, but not in one single direction
For more than twenty years, Google trained people to squeeze whatever they were thinking into a handful of words. Think “best running shoes,” or “Nike running shoes,” or even something more specific like “Nike Pegasus vs Hoka Clifton.” That habit runs deep.
ChatGPT takes away the need to compress the problem before you even ask it. People can just describe what’s actually going on.
Someone might type something like: “I’m getting back into running and doing around three 5Ks a week. I’ve heard the Nike Pegasus is good, but I’m not sure if it’s right for me. I want something cushioned and preferably under £150. What would you recommend?”
The intent underneath is exactly the same as the shorter searches above. What changes is how much context the person shares and how much reasoning they expect back in return.
When people already know precisely what they’re after, they still tend to type something short and direct. It’s really only when they’re uncertain that the conversation opens up and expands.
A spectrum, not a switch
At one end of this spectrum sit direct lookups, the kind of thing you’d type into a search bar without a second thought. At the other end sit genuinely open ended conversations, ones involving comparison, refinement and real decision making.
So the real distinction isn’t about whether the input is short or long. It comes down to whether someone is retrieving something they already know, or working towards a decision they haven’t made yet.
That’s also why keyword based habits haven’t gone away at all. They simply sit alongside this newer, more conversational style of discovery, rather than being replaced by it.
Take “Nike Pegasus 41” as an example. That reflects someone who already has prior knowledge and just wants confirmation or a spec check. Compare that to a request for the best shoe for three weekly 5Ks under £150, which demands actual evaluation and judgement before an answer can even be given.
Why multiple sources matter
No single dataset can capture the full range of how people behave in ChatGPT, so this note leans on several to build a fuller picture:
- Semrush shows observed patterns from clickstream data
- OpenAI, Harvard, Duke and NBER provide large scale usage research
- ShareChat and WildChat add further behavioural evidence on top
Put together, these sources point in the same direction even though none of them tells the whole story alone. Together they do not produce a single metric. They show how behaviour shifts with intent and certainty. ChatGPT has not replaced keywords. It has removed the requirement to use them.
When intent is clear, behaviour stays close to traditional search. When intent is unclear, the interaction becomes exploratory and conversational.
Four datasets, four different views
|
Data set |
What it contains |
Scale |
Best use |
|
Sem Rush |
Observed U.S. ChatGPT behaviour in clickstream data |
1B+ clickstream records |
Best evidence for keyword-like vs non-traditional prompt behaviour |
|
OpenAI / NBER |
Privacy-preserving classification of actual ChatGPT usage |
Representative sample |
Best evidence for what people use ChatGPT for |
|
Share Chat |
Publicly shared conversations from native chatbot platforms |
102,740 ChatGPT conversations |
Real ChatGPT prompt language; strong sharing-selection bias |
|
Wild Chat |
Natural conversations with OpenAI models via research interface |
4.74M full conversations |
Large-scale natural prompting behaviour; not representative ChatGPT.com traffic |
Semrush: how much does ChatGPT language resemble traditional search?
Semrush looked at more than one billion lines of U.S. clickstream data across both mobile and desktop, covering the period from October 2024 through to February 2026. According to Semrush, these observations came from U.S. sessions within its broader clickstream panel of 200 million users, which let it see the actual language used in each individual ChatGPT prompt within the sample, along with where people navigated to afterwards and whether ChatGPT’s web search feature was switched on at the time.
Semrush then compared this observed prompt language against its own database of more than 27 billion traditional search terms, built up over years of tracking how people use conventional search engines.
The headline numbers look like this:
- By February 2026, 34.9% of the prompts Semrush observed matched the language people typically use in traditional search
- The remaining 65.1% did not match that traditional language
- That matching share had actually climbed from just 18.9% back in October 2025, so it’s moved quite a lot in a short space of time
One thing worth being careful about here, that 65.1% figure for prompts that “did not match” shouldn’t be read as meaning two thirds of people are typing out long, conversational requests. All it really tells us is that those particular prompts weren’t close enough to the established terms sitting in Semrush’s traditional keyword database to count as a match. It’s a statement about how the language compares to existing search terms, not a direct measurement of how conversational or detailed those prompts actually were.
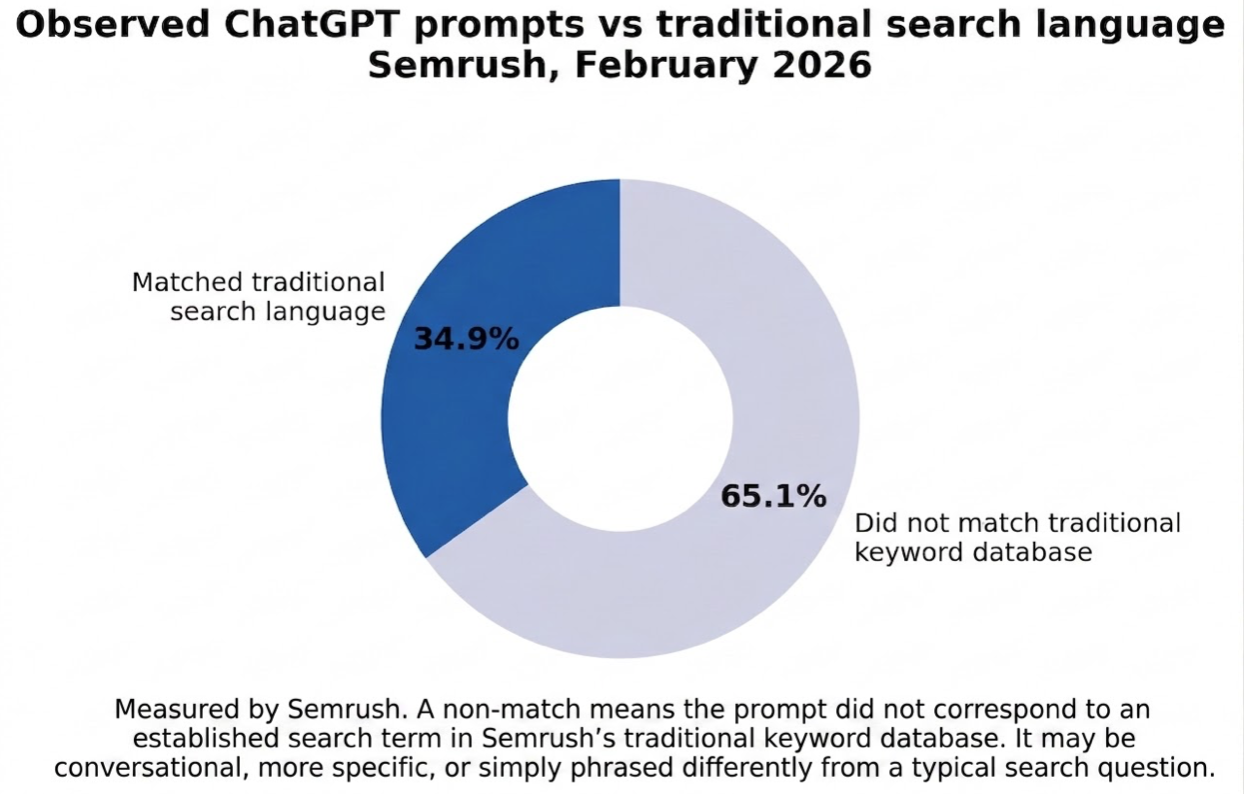
Semrush also found that the prompts resembling traditional search were disproportionately navigational and transactional. People using search-like language were mostly trying to get somewhere specific, a website, a product, a transaction, rather than exploring options.
This is central to the whole argument. When someone already knows what they want, traditional search language still does the job efficiently. There’s nothing left to figure out, so there’s no need to explain more. But as uncertainty grows, that changes. The less clear someone is about what they actually want, the more useful it becomes to add context, since that’s what lets ChatGPT reason towards an answer rather than just retrieve one.
OpenAI / Harvard / Duke / NBER: what are people actually doing in ChatGPT?
OpenAI carried out its own first-party research, published alongside researchers from Harvard and Duke as NBER Working Paper 34255. The team used a privacy-preserving automated pipeline to classify usage patterns across a representative sample of ChatGPT conversations.
What they found was that three topics dominated: Practical Guidance, Seeking Information and Writing. Together these three accounted for nearly 80% of all conversations in the sample.
This gives us genuinely high-quality evidence that information seeking, guidance and decision support make up a huge chunk of how people actually use ChatGPT. What it doesn’t give us, at least not publicly, is the raw prompt text needed to work out a proper representative split between short keyword style prompts and longer conversational ones.
ShareChat: what do real ChatGPT conversations look like?
ShareChat holds 142,808 publicly shared conversations pulled from five major chatbot platforms. The ChatGPT portion of that makes up 102,740 conversations and 542,148 individual turns, working out at an average of 5.28 turns per conversation.
The real value of ShareChat comes down to authenticity. These ChatGPT conversations come from publicly shared URLs straight off the native ChatGPT platform, which means researchers can actually look at real prompt language, see how people follow up, and study how conversations are structured.
There’s a limitation worth flagging though: these are conversations that users actively chose to share publicly. That’s a very different thing from a representative random sample of all ChatGPT traffic, so it shouldn’t be treated as one.
WildChat: natural prompting at massive scale
WildChat-4.8M offers an enormous corpus of natural human interactions with OpenAI’s models. Once you account for the removals described by the maintainers, the full dataset contains 4,743,336 conversations, with coverage running up to data collected before August 1, 2025. There’s also a non-toxic public version available, which contains 3,199,860 conversations.
What makes WildChat genuinely useful is that it captures the messy reality of how people actually type, ambiguous requests, code-switching, topics that shift mid conversation, and dialogue that runs on for a while. That said, the original WildChat collection was built by giving online users free access to GPT-3.5 and GPT-4 through the researchers’ own interface. So it’s evidence of natural GPT-style prompting in general, rather than a representative sample of what actually happens on ChatGPT.com specifically.
What the combined evidence suggests
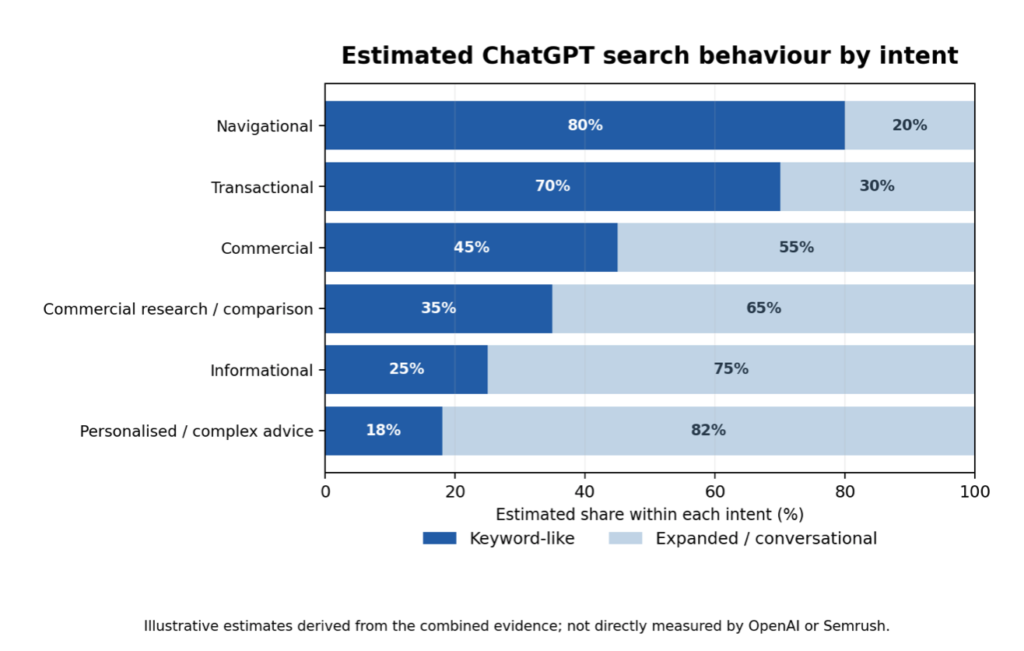
None of these datasets directly measures an intent-by-intent percentage split, and it’s important to be upfront about that. What follows below is therefore an estimate rather than a measured market statistic. The point of it is simply to take this converging body of evidence and turn it into a simple, testable behavioural hypothesis, one that can be refined further as better data comes along.
|
Intent |
Keyword- |
Prompt- |
Illustrative example |
|
Navigational |
~80% |
~20% |
nike website → nike website |
|
Transactional |
~70% |
~30% |
buy nike pegasus 41 → where can I buy Nike Pegasus 41? |
|
Commercial |
~45% |
~55% |
best nike running shoes → What are the best Nike running shoes? |
|
Commercial research |
~35% |
~65% |
nike pegasus vs hoka clifton → Which is better for 5K road running? |
|
Informational |
~25% |
~75% |
nike pegasus good for beginners → Would Pegasus suit a new runner? |
|
Personalised advice |
~18% |
~82% |
running shoes flat feet → I have flat feet, run 5Ks and want cushioning under £150. What should I buy? |
Estimate warning: these intent-level percentages have not been directly measured by OpenAI, Semrush, ShareChat or WildChat. They are illustrative estimates derived from the combined behavioural pattern across the datasets.
The Nike example: the same commercial opportunity, different language
The simplest way to understand this model is to follow one category, running shoes, and watch how the language shifts as the user’s uncertainty increases.
|
Intent |
Typical Google search |
Typical ChatGPT expression |
|---|---|---|
|
Navigational |
nike website |
nike website Why it changes: Destination already known; extra context adds little value. |
|
Transactional |
buy nike pegasus 41 |
where can I buy Nike Pegasus 41? Why it changes: Product already known; ChatGPT is mainly helping execute the task. |
|
Commercial |
best nike running shoes |
What are the best Nike running shoes at the moment? Why it changes: The category is known, but the choice is still open. |
The pattern is much easier to see as a continuum, running from someone who already knows exactly what they want, through to someone who genuinely needs help deciding.
- Knows what they want (keyword like)
- nike website
- buy nike pegasus 41
- Comparing options (mixed)
- best nike running shoes
- nike pegasus vs hoka clifton
- Needs help deciding (conversational)
- Are Nike Pegasus good for beginners?
- I’m 90kg, run 5Ks three times a week and want cushioning under £150. What would you recommend?
The change is not simply keyword to prompt
A better way to describe this shift is probably keyword to intent expression. Traditional search trained people to compress a need down into a small number of repeatable phrases. Conversational interfaces let them communicate far more of the original problem instead.
That matters a lot commercially, because one underlying need can now fragment across thousands of unique formulations. Ten thousand people might all be trying to decide which running shoes to buy without any two of them ever typing the same thing.
Keyword volume therefore stays useful, particularly for direct navigational and transactional demand, but it becomes a much less complete proxy for the total size of informational and commercial research demand happening inside AI interfaces.
Implications for SEO and GEO
Traditional SEO taught marketers to win the search term. AI search increasingly requires brands to win the conversation around the whole decision.
For Nike, that means showing up not just for “best running shoes,” but across the entire intent cluster around that decision. Things like:
- good shoes for beginners
- cushioned shoes for heavier runners
- Nike vs Hoka
- first 10K recommendations
- sub £150 choices
- Pegasus suitability
- road running use cases and alternatives
The individual prompts can look highly fragmented on the surface, while the underlying commercial demand behind them stays fairly concentrated. This is why the strategic unit of analysis may need to shift: moving away from the repeated phrase and towards the intent cluster, the problem, and the decision context around it.
Conclusion
When people know what they want, they search. When people need help deciding what they want, they prompt.That’s an estimated behavioural model rather than something directly measured or proven. But it lines up well with Semrush’s observed keyword match data, OpenAI’s first party evidence that guidance and information seeking are major use cases, and the raw conversational behaviour visible through ShareChat and WildChat.
Keywords aren’t dead. They’re becoming an incomplete measurement of demand, especially as users move away from navigation and transaction and further into research, comparison, explanation and personalised advice.
References and source notes
Semrush
1B+ U.S. clickstream records, October 2024 to February 2026. By February 2026, 34.9% of observed prompts matched traditional search language; 65.1% did not. A non-match is not the same as a long conversational prompt.
Semrush: ChatGPT traffic analysis
OpenAI / NBER
NBER Working Paper 34255 classified a representative sample of ChatGPT conversations. Practical Guidance, Seeking Information and Writing made up nearly 80% of use. It does not publish the raw prompt text needed for a keyword-versus-conversational split.
NBER Working Paper 34255 · OpenAI: How People Are Using ChatGPT
ShareChat
102,740 publicly shared ChatGPT conversations (542,148 turns). Real prompt language from the native platform, but only conversations people chose to share.
ShareChat dataset
WildChat
4.74 million conversations with OpenAI models via a research interface. Useful for natural prompting at scale; not representative of ChatGPT.com traffic.
WildChat-4.8M
What does this mean for your brand?
As search moves beyond keywords and towards intent, brands need to think about more than where they rank. They also need to understand whether their content is being found, understood and referenced when people ask AI platforms for information, comparisons and recommendations.
Our Answer Engine Optimisation (AEO) services help brands build visibility across AI-driven search, from understanding where the opportunities lie to improving the content, structure and authority signals that influence how brands appear in AI-generated answers.
